Showing posts with label nanopore. Show all posts

Tuesday, 5 November 2024

#ABACBS2024 Poster 102: Improving phased Hifiasm assemblies with 20 kb ONT reads

After a great presentation this morning by Emma de Jong on our High-Quality Genomes for Australian Lutjanidae Species (abstract below), if you’re at ABACBS2024 then please drop by Poster #102 to find out about some of the work we’re doing with ONT data.

Abstracts

Improving phased Hifiasm assemblies with 20 kb ONT reads

Richard J Edwards, Adrianne Doran, Emma de Jong, Lara Parata, Shannon Corrigan

The quality and quantity of genome assembly has improved dramatically over recent years. Many large-scale genome projects combine assembly of HiFi and HiC reads using Hifiasm to produce contiguous phased assemblies, scaffolded to chromosome-level. Nevertheless, HiFi reads are typically under 25 kb and can still struggle to assemble long, low diversity repeat regions. Obtaining ultra-long (100 kb or longer) ONT reads to solve this problem remains a significant challenge due to technical constraints and DNA sample requirements. Here, we explore the utility of using standard ONT long reads (20 kb or more) as “ultra-long” input to improve phased Hifiasm assemblies for 22 species of bony fish (Genome Size, 627 Mb 1.54 Gb). We also explore whether the new --telo-m mode in Hifiasm v0.9.0 improves telomere prediction. Incorporating 20kb+ ONT reads (7.8X 93.5X) significantly increased assembly contiguity. BUSCO Completeness was not significantly altered, although there was some re-partitioning of BUSCO genes between phased haplotypes for some species. Improvement did not strongly correlate with read depth (either HiFi or ONT), suggesting that the underlying read length distributions and/or specific genome features are more important for determining the outcome. Hifiasm --telo-m mode significantly increased telomere recovery, assembling over six times the number of gapless telomere-to-telomere chromosomes when combined with 20kb+ ONT reads. Verification of how these results translate to the ease of curation and/or quality of final HiC-scaffolded chromosome-level assemblies is ongoing, with a goal to determine whether the additional sample preparation and sequencing in the lab is cost-effective.

High-Quality Genomes for Australian Lutjanidae Species

Emma de Jong, Lara Parata, Philipp E Bayer, Shannon Corrigan, Richard J Edwards

Lutjanidae (snappers) are highly valued in commercial and recreational fisheries worldwide and serve as indicator species of the health of marine environments and fishery bioregions in Western Australia. Comprehensive genomic mapping of immune gene families of Lutjanidae species are lacking, but this information is critical for understanding disease vulnerability, the impact of environmental stress, improving aquaculture efforts and to provide insights into the health of wild populations. Despite their importance, only 3 out of 113 Lutjanid species currently have available reference genomes, two of which are highly fragmented (>11,000 and >200,000 contigs), impacting studies on gene families relevant to aquaculture. In this study, we present high-quality chromosome-level reference genomes for 14 Australian Lutjanidae species across seven genera, generated using HiFi and HiC data. We present initial comparative genomic analyses, including immune gene content and chromosomal synteny analyses across species. These analyses provide insights into the genomic architecture and evolutionary relationships within Lutjanidae. Ongoing work aims to comprehensively map and compare the immune gene family repertoire across Lutjanidae genera, as well as Lethrinidae species as an outgroup, to determine genus-specific changes in genes (e.g. loss, selection, duplication) important for pathogen detection, antigen presentation, inflammation, and immune memory. These genome assemblies will serve as a foundational resource to the wider scientific community interested in Lutjanidae

Sunday, 3 November 2024

Chromosome-level genome assembly of the Australian rainforest tree Rhodamnia argentea (malletwood)

Genome projects don’t always go according to plan, and when we first sequenced Rhodamnia argentea with 10x Genomics linked reads, we accidentally sequenced a parasite along with it. This was quite hard to identify from the sequencing data itself, as the depth of sequencing was quite high, and we were unable to identify the guilty bug itself, which is probably microscopic. Getting to the bottom of this took a back seat for a while when the focus of the project shifted to Melaleuca quinquenervia, but with the addition of ONT reads and Hi-C, we have now been able to generate a chromosome-level decontaminated assembly. (An assembly of the contaminating mite will follow…)

Chen SH, Jones A, Lu-Irving P, Yap JYS, van der Merwe M, Bragg JG & Edwards RJ (2024): Chromosome-level genome assembly of the Australian rainforest tree Rhodamnia argentea (malletwood). Genome Biology and Evolution 16(11):evae238. [Gen Biol Evol] [PubMed]

Abstract

Myrtaceae are a large family of woody plants, including hundreds that are currently under threat from the global spread of a fungal pathogen, Austropuccinia psidii (G. Winter) Beenken, which causes myrtle rust. A reference genome for the Australian native rainforest tree Rhodamnia argentea Benth. (malletwood) was assembled from Oxford Nanopore Technologies long-reads, 10x Genomics Chromium linked-reads, and Hi-C data (N50 = 32.3 Mb and BUSCO completeness 98.0%) with 99.0% of the 347 Mb assembly anchored to 11 chromosomes (2n = 22). The R. argentea genome will inform conservation efforts for Myrtaceae species threatened by myrtle rust, against which it shows variable resistance. We observed contamination in the sequencing data, and further investigation revealed an arthropod source. This study emphasizes the importance of checking sequencing data for contamination, especially when working with nonmodel organisms. It also enhances our understanding of a tree that faces conservation challenges, contributing to broader biodiversity initiatives.

Thursday, 31 October 2024

BioDiversity Genomics Conference (BG24)

The global BioDiversity Genomics Conference (BG24) was another great success this year. As well as running a session on Marine Vertebrate Genomics, it was particularly rewarding to see some many quality contributions from lab members and alumni.

Biodiversity Genomics in Australasia

Jessica Pearce (UWA): Reconstructing tiger shark history using genomics

Sharks and rays are a clade of high evolutionary, ecological, economic, and cultural significance, and yet they are one of the most threatened taxa groups in the marine environment. Despite this, there remains a lack of molecular resources for this class to assist with their conservation. The tiger shark (Galeocerdo cuvier) is a near threatened, keystone species distributed circumglobally that is under substantial pressure from human impacts, making it a high priority for management worldwide. We sequenced and characterised a reference quality assembly for the tiger shark, the first genome for this family, and used this to dive deeper into the evolution, adaption, and demographic history of this ancient species. We investigated how its effective population size (Ne), genome-wide heterozygosity and inbreeding has changed over time to infer how this species has responded to past global events, and hence potential responses to ongoing and future accumulating threats. This aims to assist in effective management of this high-profile species. 

Katarina Stuart (University of Auckland): Lifetime fitness is correlated more strongly with structural variant than SNP mutational load in a threatened bird species

Conservation genomics is becoming increasingly interested in whether structural variant (SV) information can help the management of threatened species. The functional consequences of SVs are more complex than for single nucleotide polymorphisms (SNPs) and thus may be more likely to contribute to load. While the impacts of SV-specific genetic load may be less consequential for large populations, the interplay between weakened selection and stochastic processes mean that smaller populations, like those of the threatened Aotearoa hihi/New Zealand stitchbird (Notiomystis cincta), may harbour a high SV load. Hihi were once confined to a single remnant population, but have been reestablished into six sanctuaries and reserves, often via secondary bottlenecks, resulting in low genetic diversity, low adaptive potential and inbreeding depression. In this study, we use whole genome resequencing of 30 individuals from the Tiritiri Matangi population to identify the nature and distribution of both SNPs and SVs within this small avian population. We find that SNP and SV individual mutation load is only moderately correlated, likely because SVs arise in regions of high recombination and reduced evolutionary conservation. Finally, we leverage a long-term monitoring dataset of pedigree and fitness data to assess the impact of SNP and SV mutation load on individual fitness, and demonstrate that SV load correlates more strongly than SNP load with lifetime fitness. The results of this study indicate that only examining SNPs neglects important aspects of intraspecific variation, and that studying SVs has direct implications for linking genetic diversity and genetic health to inform management decisions.

Richard Edwards (UWA): Improving Hifiasm assemblies with 20 kb ONT reads

The quality and quantity of genome assembly has improved dramatically over recent years. Many large-scale genome projects assemble HiFi and HiC reads using Hifiasm to produce contiguous phased assemblies, scaffolded to chromosome-level. Nevertheless, HiFi reads are typically under 25 kb and can still struggle to assemble long, low-diversity repeat regions. Obtaining ‘ultra-long’ (100 kb or longer) ONT reads to solve this problem remains a significant challenge due to technical constraints and DNA sample requirements. Here, we explore the utility of using standard ONT long reads (20 kb or more) as ‘ultra-long’ input to improve phased Hifiasm assemblies for 22 species of bony fish (Genome Size, 627 Mb - 1.54 Gb). We also explore whether the new ‘telo-m’ mode in Hifiasm v0.9.0 improves telomere prediction in these species. Incorporating 20+ kb ONT reads (7.8X - 93.5X) significantly increased assembly contiguity. BUSCO completeness was not significantly altered, although there was some re-partitioning of BUSCO genes between phased haplotypes for some species. Improvement did not strongly correlate with read depth (neither HiFi nor ONT), suggesting that the underlying read length distributions and/or specific genome features are more important for determining the outcome. Hifiasm ‘telo-m’ mode significantly increased telomere recovery, assembling over six times the number of gapless telomere-to-telomere chromosomes when combined with incorporation of ONT reads. Verification of how these results translate to the quality and/or ease of curation of final HiC-scaffolded chromosome-level assemblies is ongoing, with a goal to determine whether the additional sample preparation and sequencing in the lab is cost-effective.

Emma de Jong (UWA): High-Quality Genomes for Australian Lutjanidae Species

Lutjanidae (snappers) are highly valued in commercial and recreational fisheries worldwide and some species serve as fisheries indicator species particularly for bioregions in Western Australia. Comprehensive genomic mapping of immune gene families of Lutjanidae species are lacking, but this information can inform understanding disease vulnerability, the impact of environmental stress, improving aquaculture efforts and to provide insights into the health of wild populations. Despite their importance, only 3 out of 113 Lutjanid species currently have available reference genomes, two of which are highly fragmented (>11,000 and >200,000 contigs), impacting studies on gene families relevant to aquaculture. In this study, we present high-quality chromosome-level reference genomes for 14 Australian lutjanid species across seven genera, generated using PacBio HiFi and Dovetail HiC data. We present initial comparative genomic analyses, including immune gene content and chromosomal synteny analyses across species. These analyses provide insights into the genomic architecture and evolutionary relationships within Lutjanidae. Ongoing work aims to comprehensively map and compare the immune gene family repertoire across genera in Lutjanidae, as well as lethrinid species as an outgroup, to determine genus-specific changes in genes (e.g., loss, selection, duplication) important for pathogen detection, antigen presentation, inflammation, and immune memory. These genome assemblies will serve as a foundational resource to the wider scientific community interested in these species.

Research of ECRs who work in biodiversity genomics

Lara Parata (UWA): Genome Evolution in Marine Ray-Finned Fishes

Approximately half of extant vertebrate species are fishes, with more than 30,000 species classified as ray-finned fishes (Actinopterygii). Actinopterygii represent diverse phenotypes, feeding strategies, life history traits and occupy distinct ecological niches, making them an ideal taxa for studying molecular drivers of diversity and adaptation. Despite their diversity, ecological, and economical importance, only 145 Illumina genome assemblies are available for marine Actinopterygii species. In this study we present 250 new marine Actinopterygii genome assemblies generated using Illumina whole genome sequencing and initial results from a large-scale study of these 395 genomes. Using reference-based annotation tools we determine which fish families have unique patterns of gene family frequency / structure (e.g., losses, expansions, contractions), and correlate these with predicted functional signatures to infer biological and ecological adaptations. We identify fish families with distinct rates of change in the gene families present within their genomes (e.g., more losses / expansions or diversity) and associate these patterns with increased rates of diversification or speciation to further elucidate the genomic attributes contributing to ecological success. The results of this work contribute to the growing understanding of fish genome evolution and provide new insights into the evolutionary history and ecological success of marine Actinopterygii.

Friday, 15 March 2024

Towards telomere-to-telomere fish genomes with Oxford Nanopore Technologies gap-filling

It was a pleasure to be invited to the “What You’re Missing Matters” tour at Perth, and present some ongoing work investigating the best way to incorporate Oxford Nanopore Technologies data into our high-quality HiFi+HiC fish genomes. The results are too preliminary to share here (and will soon be superseded) but do get in touch if it sounds interesting to you.

Friday, 15 December 2023

A high-quality pseudo-phased genome for Melaleuca quinquenervia shows allelic diversity of NLR-type resistance genes

Chen SH, Martino AM, Luo Z, Schwessinger B, Jones A, Tolessa T, Bragg JG, Tobias PA, Edwards RJ (2023): A high-quality pseudo-phased genome for Melaleuca quinquenervia shows allelic diversity of NLR-type resistance genes. GigaScience 12:giad102. [Gigascience] [PubMed]

Background. Melaleuca quinquenervia (broad-leaved paperbark) is a coastal wetland tree species that serves as a foundation species in eastern Australia, Indonesia, Papua New Guinea, and New Caledonia. While extensively cultivated for its ornamental value, it has also become invasive in regions like Florida, USA. Long-lived trees face diverse pest and pathogen pressures, and plant stress responses rely on immune receptors encoded by the nucleotide-binding leucine-rich repeat (NLR) gene family. However, the comprehensive annotation of NLR encoding genes has been challenging due to their clustering arrangement on chromosomes and highly repetitive domain structure; expansion of the NLR gene family is driven largely by tandem duplication. Additionally, the allelic diversity of the NLR gene family remains largely unexplored in outcrossing tree species, as many genomes are presented in their haploid, collapsed state.

Results. We assembled a chromosome-level pseudo-phased genome for M. quinquenervia and described the allelic diversity of plant NLRs using the novel FindPlantNLRs pipeline. Analysis reveals variation in the number of NLR genes on each haplotype, distinct clustering patterns, and differences in the types and numbers of novel integrated domains.

Conclusions. The high-quality M. quinquenervia genome assembly establishes a new framework for functional and evolutionary studies of this significant tree species. Our findings suggest that maintaining allelic diversity within the NLR gene family is crucial for enabling responses to environmental stress, particularly in long-lived plants.

Wednesday, 29 March 2023

The Australasian dingo archetype: De novo chromosome-length genome assembly, DNA methylome, and cranial morphology

Ballard JWO, Field MA, Edwards RJ, Wilson LAB, Koungoulos LG, Rosen BD, Chernoff B, Dudchenko O, Omer A, Keilwagen J, Skvortsova K, Bogdanovic O, Chan E, Zammit R, Hayes V & Aiden EL (2023): The Australasian dingo archetype: De novo chromosome-length genome assembly, DNA methylome, and cranial morphology. Gigascience 12:giad018. [Gigascience] [PubMed]

Background

One difficulty in testing the hypothesis that the Australasian dingo is a functional intermediate between wild wolves and domesticated breed dogs is that there is no reference specimen. Here we link a high-quality de novo long-read chromosomal assembly with epigenetic footprints and morphology to describe the Alpine dingo female named Cooinda. It was critical to establish an Alpine dingo reference because this ecotype occurs throughout coastal eastern Australia where the first drawings and descriptions were completed.

Findings

We generated a high-quality chromosome-level reference genome assembly (Canfam_ADS) using a combination of Pacific Bioscience, Oxford Nanopore, 10X Genomics, Bionano, and Hi-C technologies. Compared to the previously published Desert dingo assembly, there are large structural rearrangements on chromosomes 11, 16, 25, and 26. Phylogenetic analyses of chromosomal data from Cooinda the Alpine dingo and 9 previously published de novo canine assemblies show dingoes are monophyletic and basal to domestic dogs. Network analyses show that the mitochondrial DNA genome clusters within the southeastern lineage, as expected for an Alpine dingo. Comparison of regulatory regions identified 2 differentially methylated regions within glucagon receptor GCGR and histone deacetylase HDAC4 genes that are unmethylated in the Alpine dingo genome but hypermethylated in the Desert dingo. Morphologic data, comprising geometric morphometric assessment of cranial morphology, place dingo Cooinda within population-level variation for Alpine dingoes. Magnetic resonance imaging of brain tissue shows she had a larger cranial capacity than a similar-sized domestic dog.

Conclusions

These combined data support the hypothesis that the dingo Cooinda fits the spectrum of genetic and morphologic characteristics typical of the Alpine ecotype. We propose that she be considered the archetype specimen for future research investigating the evolutionary history, morphology, physiology, and ecology of dingoes. The female has been taxidermically prepared and is now at the Australian Museum, Sydney.

Thursday, 6 October 2022

The Ocean Genomes Laboratory is hiring!

The Minderoo OceanOmics Centre at UWA Ocean Genomes Laboratory is now hiring our technical team to support high throughput DNA sequencing and genome assembly. We currently have three "wet" lab positions going: a Sequencing Specialist Scientific Officer, and two Sequencing Technician positions. Both roles will be providing technical support in the lab, particularly with respect to all aspects of DNA sequencing (sample extraction, library preparation and setting up sequencing runs). You'll get to play with the latest sequencing toys, including Illumina NovaSeq 6000, NextSeq 2000 and iSeq 100, the PacBio Sequel IIe, and ONT (probably PromethION and MinION).

The closing date for applications is 11:55 PM AWST on Thursday 27 October 2022.

To learn more about these opportunities, please click on the links above or contact Rich Edwards at rich.edwards@uwa.edu.au. We will also be advertising some bioinformatics positions soon.

About the team

The Minderoo OceanOmics Centre at UWA combines a joint Ocean Genomes Laboratory, an OceanOmics Laboratory, and Computational Biology Services.

Equipped with the latest high-throughput sequencing technology and in collaboration with global partners, the Ocean Genomes Laboratory will generate a comprehensive library of high quality marine vertebrate reference genome assemblies. All such reference genome data will be subject to rigorous QA/QC and all assemblies will be released publicly with open access.

The Ocean Genomes Laboratory will undertake research and development under the direction of Minderoo’s ambitious OceanOmics Program which has the goal of revolutionising ocean conservation through novel marine sampling and genomics approaches and scaling these to significantly advance our knowledge of marine life. The Ocean Genomes Laboratory and Computational Biology Services will include state of the art infrastructure including sample and eDNA preparation areas, flow cytometry, single cell sequencing equipment and the latest bioinformatics and computational biology tools.

Wednesday, 29 June 2022

The starling genome is out!

See the pre-print post for details.

Stuart KC*, Edwards RJ*, Cheng Y, Warren WC, Burt DW, Sherwin WB, Hofmeister NR, Werner SJ, Ball GF, Bateson M, Brandley MC, Buchanan KL, Cassey P, Clayton DF, De Meyer T, Meddle SL & Rollins LA (2022): Transcript- and annotation-guided genome assembly of the European starling. Molecular Ecology 22(8):3141-3160. doi: 10.1111/1755-0998.13679. [*Joint first authors] [Mol Ecol Res] [PubMed] [bioRxiv]

The European starling, Sturnus vulgaris, is an ecologically significant, globally invasive avian species that is also suffering from a major decline in its native range. Here, we present the genome assembly and long-read transcriptome of an Australian-sourced European starling (S. vulgaris vAU), and a second, North American, short-read genome assembly (S. vulgaris vNA), as complementary reference genomes for population genetic and evolutionary characterization. S. vulgaris vAU combined 10× genomics linked-reads, low-coverage Nanopore sequencing, and PacBio Iso-Seq full-length transcript scaffolding to generate a 1050 Mb assembly on 6222 scaffolds (7.6 Mb scaffold N50, 94.6% busco completeness). Further scaffolding against the high-quality zebra finch (Taeniopygia guttata) genome assigned 98.6% of the assembly to 32 putative nuclear chromosome scaffolds. Species-specific transcript mapping and gene annotation revealed good gene-level assembly and high functional completeness. Using S. vulgaris vAU, we demonstrate how the multifunctional use of PacBio Iso-Seq transcript data and complementary homology-based annotation of sequential assembly steps (assessed using a new tool, saaga) can be used to assess, inform, and validate assembly workflow decisions. We also highlight some counterintuitive behaviour in traditional busco metrics, and present buscomp, a complementary tool for assembly comparison designed to be robust to differences in assembly size and base-calling quality. This work expands our knowledge of avian genomes and the available toolkit for assessing and improving genome quality. The new genomic resources presented will facilitate further global genomic and transcriptomic analysis on this ecologically important species.

Friday, 14 January 2022

The Waratah genome paper is out!

The final version of the waratah genome paper now out in Molecular Ecology Resources. This was a fun collaboration with the Royal Botanic Gardens and Domain Trust as one of the pilot genomes for BioPlatforms Australia’s Genomics for Australian Plants (GAP) initiative.

You can read the press release here, or our piece in the Conversation, We’ve unveiled the waratah’s genetic secrets, helping preserve this Australian icon for the future.

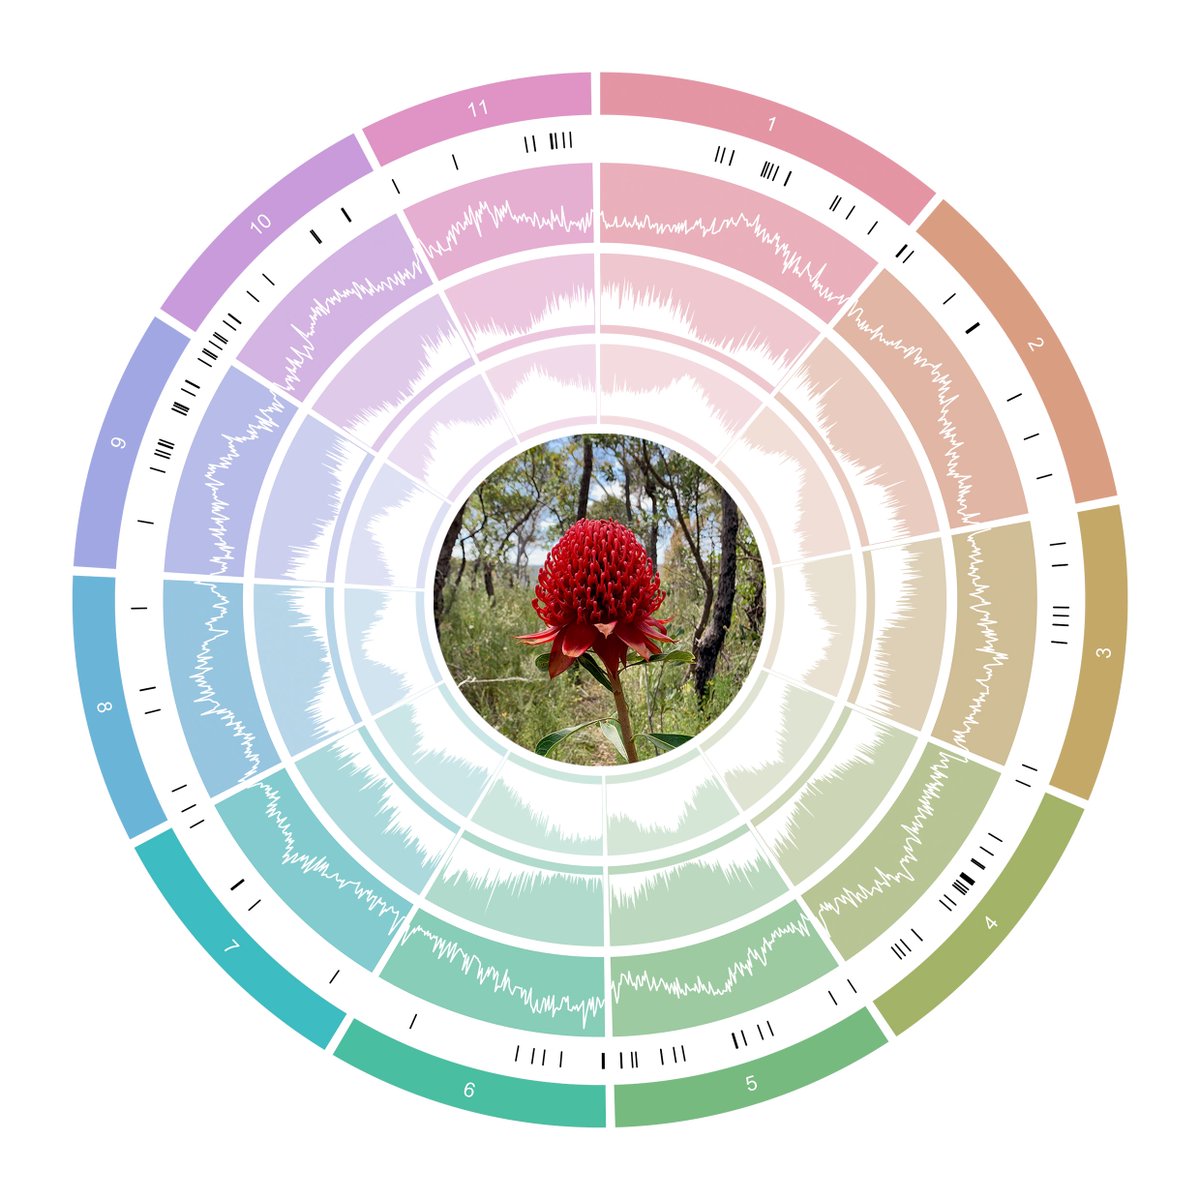
In this paper, we present a chromosome-level assembly for the NSW State Floral Emblem, the New South Wales waratah, Telopea speciosissima. This joins macadamia as the 2nd reference genome for the Proteaceae family & should help future studies for the remaining ca. 1700 species.

The genome was assembled from a ONT chassis, scaffolded with 10x Genomics linked reads and Phase Genomics HiC - made possible thanks to quality data from AGRF and the Ramaciotti Centre for Genomics. The final assembly was chromosome-level, with 94.1% on the 11 chromosomes (2n = 22).

As well as the assembly itself, the paper presents a three genomics tools that we hope will be helpful for other assemblies:

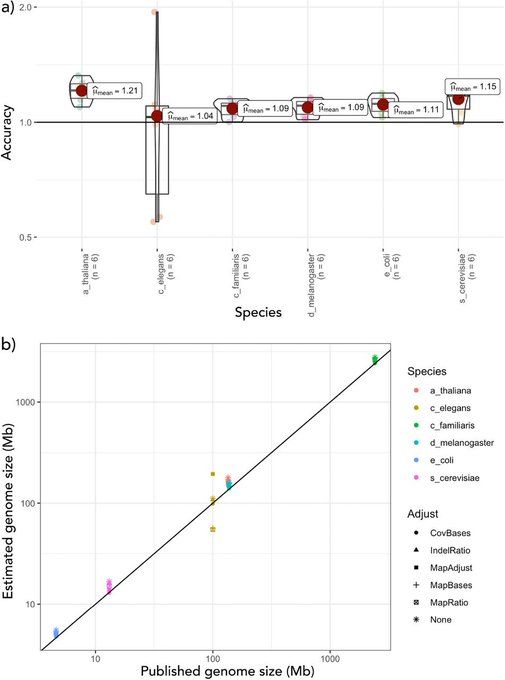
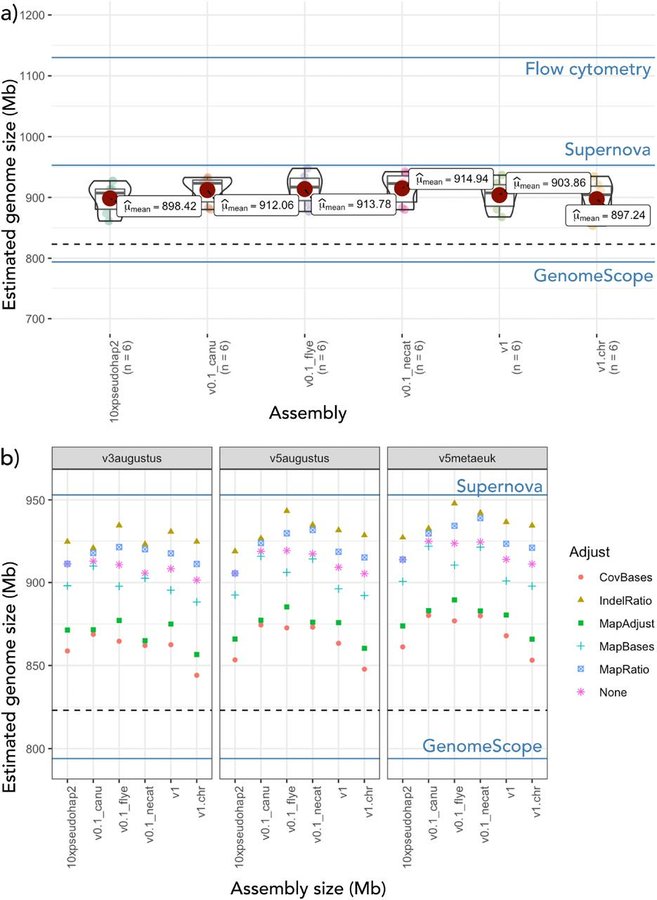
1. DepthSizer uses long-read depths and BUSCO predictions to estimate genome size. We estimated the waratah genome to be ca. 900 Mbp - bigger than kmer estimates, but smaller than flow cytometry of Tasmanian waratah.

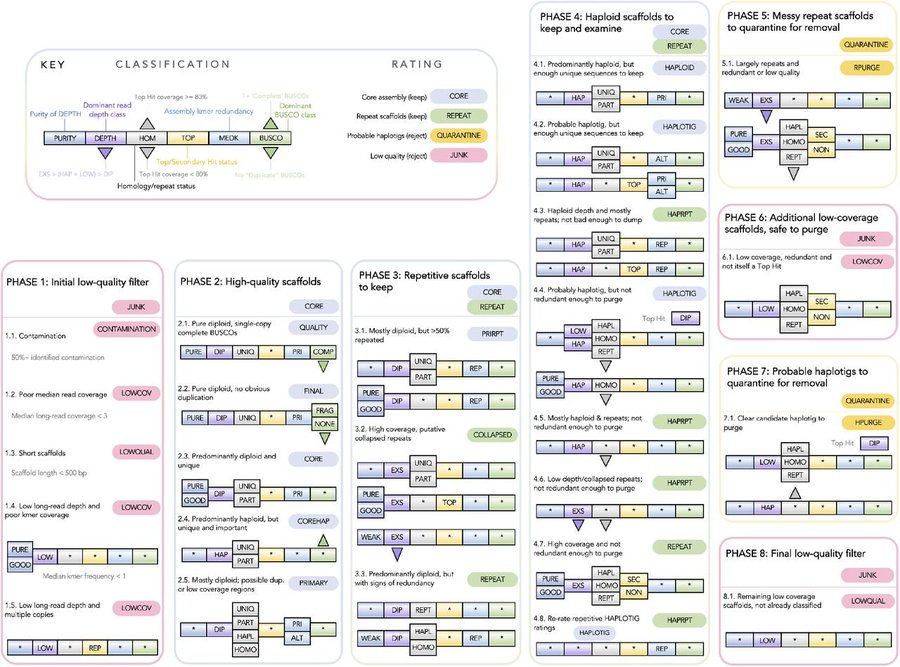
2. Diploidocus builds on Purge Haplotigs, combining read depths, kmer frequencies & BUSCO predictions to classify and curate/filter assembly scaffolds. This decreases false duplications & contamination, and flags collapsed repeats for closer inspection.

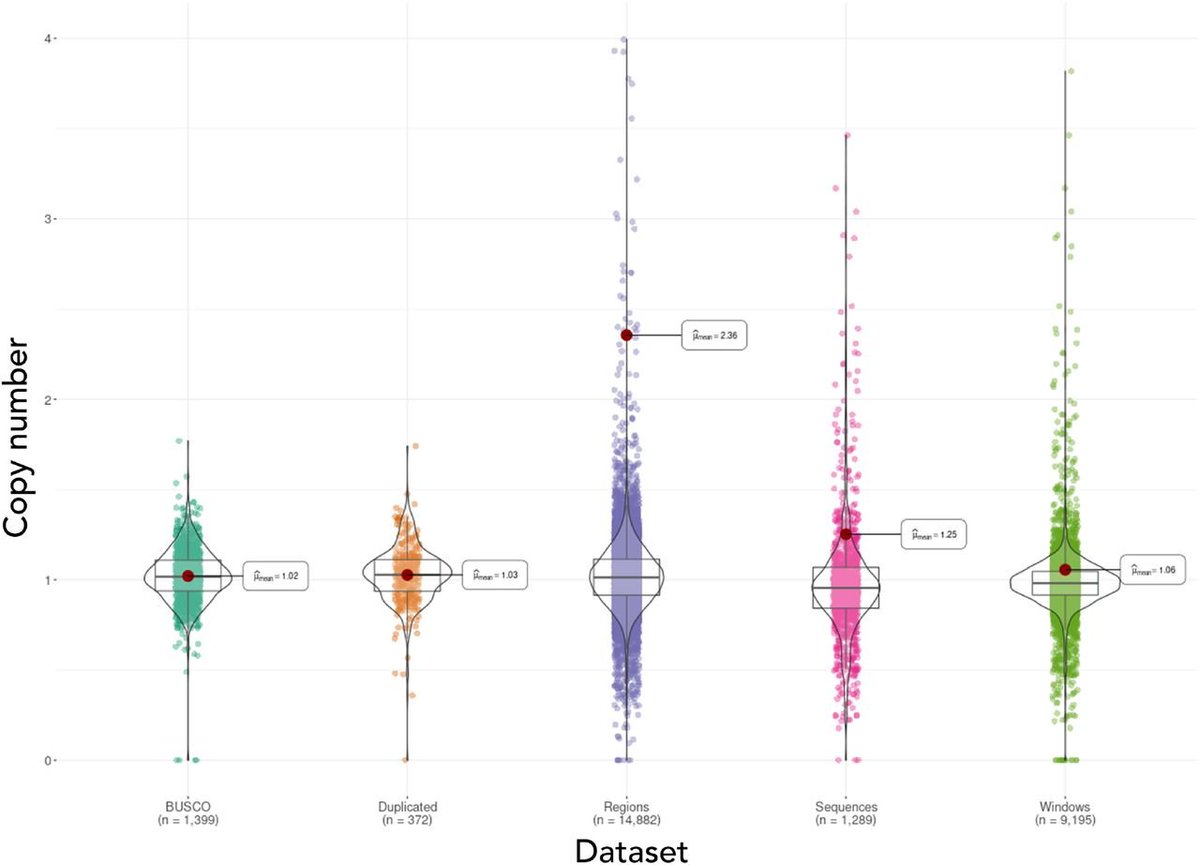
3. DepthKopy uses BUSCO Complete genes to establish sequencing depth (like DepthSizer) and then estimates copy number for regions (e.g. genes), scaffolds & sliding windows of the assembly. This showed that most “Duplicated” BUSCOs are real duplicates.


Chen SH, Rossetto M, van der Merwe M, Lu-Irving P, Yap JS, Sauquet H, Bourke G, Amos TG, Bragg JG & Edwards RJ (accepted): Chromosome-level de novo genome assembly of Telopea speciosissima (New South Wales waratah) using long-reads, linked-reads and Hi-C. Molecular Ecology Resources.
[Mol Ecol Res] [bioRxiv]

Abstract

Telopea speciosissima, the New South Wales waratah, is an Australian endemic woody shrub in the family Proteaceae. Waratahs have great potential as a model clade to better understand processes of speciation, introgression and adaptation, and are significant from a horticultural perspective. Here, we report the first chromosome-level genome for T. speciosissima. Combining Oxford Nanopore long-reads, 10x Genomics Chromium linked-reads and Hi-C data, the assembly spans 823 Mb (scaffold N50 of 69.0 Mb) with 97.8% of Embryophyta BUSCOs “Complete”. We present a new method in Diploidocus (https://github.com/slimsuite/diploidocus) for classifying, curating and QC-filtering scaffolds, which combines read depths, k-mer frequencies and BUSCO predictions. We also present a new tool, DepthSizer (https://github.com/slimsuite/depthsizer), for genome size estimation from the read depth of single-copy orthologues and estimate the genome size to be approximately 900 Mb. The largest 11 scaffolds contained 94.1% of the assembly, conforming to the expected number of chromosomes (2n = 22). Genome annotation predicted 40,158 protein-coding genes, 351 rRNAs and 728 tRNAs. We investigated CYCLOIDEA (CYC) genes, which have a role in determination of floral symmetry, and confirm the presence of two copies in the genome. Read depth analysis of 180 “Duplicated” BUSCO genes using a new tool, DepthKopy (https://github.com/slimsuite/depthkopy), suggests almost all are real duplications, increasing confidence in the annotation and highlighting a possible need to revise the BUSCO set for this lineage. The chromosome-level T. speciosissima reference genome (Tspe_v1) provides an important new genomic resource of Proteaceae to support the conservation of flora in Australia and further afield.

If you want a read and don’t have access, please get it touch or check out the bioRxiv preprint.

Wednesday, 24 November 2021

#ABACBS2021 Lightning talk - DepthSizer and DepthKopy: genome size and copy number prediction using single-copy long-read depth profiles

Tune in for the ABACBS 2021 lightning talks this morning to hear about our applications of long reads to genome size and copy number prediction. For more information, you can read the NSW Waratah genome paper pre-print or visit the GitHub pages for DepthSizer and DepthKopy.

Richard J Edwards, Stephanie H Chen, Katarina C Stuart, Mark M Tanaka, Jason G Bragg.

DepthSizer and DepthKopy: genome size and copy number prediction using single-copy long-read depth profiles

A fundamental part of any genome project is establishing the genome size of the organism being sequenced. The gold standard for genome size measurement is flow cytometry, but this is not available to all groups and can give surprisingly variable results. Popular bioinformatic approaches predict genome size using kmer frequency profiles from high-accuracy (e.g. illumina or hifi) sequencing reads, or the mean depth of coverage reads mapped to an assembly. Both of these approaches can be adversely affected by repetitive regions of the genome. Mean sequencing depth is also highly reliant on assembly completeness.

Here, we present DepthSizer (https://github.com/slimsuite/depthsizer), which refines this approach by estimating sequencing depth based on single-copy complete BUSCO genes. DepthSizer works on the principle that genuine single-copy regions will tend towards the same, true, single-copy read depth. In contrast, assembly errors, collapsed repeats within those genes, or incorrect BUSCO predictions, will give inconsistent read depth deviations. The modal read depth across single-copy BUSCO genes, calculated from a depth density profile of these regions, should therefore provide a good estimate of the true depth of coverage. The method is benchmarked on model organism data and corrections for possible contamination, biases/inconsistencies in read mapping and/or raw read insertion/deletion error profiles are discussed. We also present DepthKopy (https://github.com/slimsuite/depthkopy), which uses the same read depth approach to estimate the copy number of assembly regions. This can be useful for identifying haplotigs, and collapsed repeat regions.

Keywords: BUSCO, Genome Assembly, Genomics, ONT, PacBio, copy number variants

Thursday, 3 June 2021

Chromosome-level de novo genome assembly of Telopea speciosissima (New South Wales waratah) using long-reads, linked-reads and Hi-C

The latest genomics paper from the lab is now out on bioRvix. This is the first paper from Stephanie Chen’s PhD project in collaboration with the Royal Botanic Gardens and Domain Trust (RBGDT), Sydney. In this paper, Stephanie reports on the chromosome-level assembly of the New South Wales Waratah, the floral emblem of NSW. This is the first of the pilot reference genomes to be released from the Genomics for Australian Plants initiative.

In addition to the genome itself, this paper describes a couple of genomics tools from the lab. DepthSizer (https://github.com/slimsuite/depthsizer) uses BUSCO predictions to establish the single-copy read depth of sequencing data, from which the genome size can be estimated in a way that is hopefully quite robust to assembly quality. Diploidocus (https://github.com/slimsuite/diploidocus) has been used for our previous Dog genome assemblies to help eliminate “haplotigs” (heterozygous regions of the genome that appear in the assembly twice), and low-quality sequences, in addition to flagging possible collapsed repeats or contaminants for further investigation. Here, the Diploidocus “tidy” pipeline is considerably extended for a much more nuanced classification and filtering of scaffolds, using a combination of read depths, homology, kmer analysis and BUSCO predictions.


Chen SH, Rossetto M, van der Merwe M, Lu-Irving P, Yap JS, Sauquet H, Bourke G, Bragg JG & Edwards RJ (preprint): Chromosome-level de novo genome assembly of Telopea speciosissima (New South Wales waratah) using long-reads, linked-reads and Hi-C. bioRxiv 2021.06.02.444084; doi: 10.1101/2021.06.02.444084.
[bioRxiv]

Abstract

Background: Telopea speciosissima, the New South Wales waratah, is Australian endemic woody shrub in the family Proteaceae. Waratahs have great potential as a model clade to better understand processes of speciation, introgression and adaptation, and are significant from a horticultural perspective. Findings: Here, we report the first chromosome-level reference genome for T. speciosissima. Combining Oxford Nanopore long-reads, 10x Genomics Chromium linked-reads and Hi-C data, the assembly spans 823 Mb (scaffold N50 of 69.0 Mb) with 91.2 % of Embryophyta BUSCOs complete. We introduce a new method in Diploidocus (https://github.com/slimsuite/diploidocus) for classifying, curating and QC-filtering assembly scaffolds. We also present a new tool, DepthSizer (https://github.com/slimsuite/depthsizer), for genome size estimation from the read depth of single copy orthologues and find that the assembly is 93.9 % of the estimated genome size. The largest 11 scaffolds contained 94.1 % of the assembly, conforming to the expected number of chromosomes (2n = 22). Genome annotation predicted 40,158 protein-coding genes, 351 rRNAs and 728 tRNAs. Our results indicate that the waratah genome is highly repetitive, with a repeat content of 62.3 %. Conclusions: The T. speciosissima genome (Tspe_v1) will accelerate waratah evolutionary genomics and facilitate marker assisted approaches for breeding. Broadly, it represents an important new genomic resource of Proteaceae to support the conservation of flora in Australia and further afield.

Thursday, 8 April 2021

Transcript- and annotation-guided genome assembly of the European starling

Our starling genome paper is now available as a pre-print on bioRxiv! This was some great work by PhD student, Kat Stuart. Kat assembled a new Australian starling genome, using a combination of linked reads, low coverage long reads, and long-read PacBio iso-seq transcriptomics data. A second Illumina assembly of a North American group is also presented. As we saw with our Basenji genome paper, having two (or more) genomes from a species can be really useful for disentangling real difference from assembly artefacts. (No assembly is perfect!)

This paper is a great example of how a bit of TLC and imagination can get the most out of data produced with a limited budget. We were unable to get deep long-read sequencing this time, but instead show the additional power that long-read full-length transcriptome data can provide in assembling a genome - above and beyond the annotation.

This paper also officially describes a couple of genomics tools from the lab BUSCOMP has been in the works for some time, and this paper updates previous results to BUSCO v5 analysis and confirms our previous snake results using starling-derived test data. BUSCO is a powerful and popular tool that estimates genome completeness using gene prediction and curated models of single-copy protein orthologues. However, we demonstrate how results can be counterintuitive: adding/removing scaffolds can alter BUSCO predictions elsewhere in the assembly, while low sequence quality may reduce “completeness” scores and miss genes that are present in the assembly. BUSCOMP (BUSCO Compilation and Comparison) (https://github.com/slimsuite/buscomp) complements BUSCO to identify/overcome these issues by compiling a non-redundant set of the highest-scoring single-copy BUSCO complete sequences and re-searching these against assemblies for consistent completness scoring. SAAGA (https://github.com/slimsuite/saaga) is a new tool for annotation versus reference proteome comparisons. SAAGA can compare different annotations of the same assembly, or be combined with a lightweight annotation tool like GeMoMa to compare different assemblies of the same organism.


Stuart KC, Edwards RJ, Cheng Y, Warren WC, Burt DW, Sherwin WB, Hofmeister NR, Werner SJ, Ball GF, Bateson M, Brandley MC, Buchanan KL, Cassey P, Clayton DF, De Meyer T, Meddle SL & Rollins LA (preprint): Transcript- and annotation-guided genome assembly of the European starling. bioRxiv 2021.04.07.438753; doi: 10.1101/2021.04.07.438753. [*Joint first authors] [bioRxiv]

Abstract

The European starling, Sturnus vulgaris, is an ecologically significant, globally invasive avian species that is also suffering from a major decline in its native range. Here, we present the genome assembly and long-read transcriptome of an Australian-sourced European starling (S. vulgaris vAU), and a second North American genome (S. vulgaris vNA), as complementary reference genomes for population genetic and evolutionary characterisation. S. vulgaris vAU combined 10x Genomics linked-reads, low-coverage Nanopore sequencing, and PacBio Iso-Seq full-length transcript scaffolding to generate a 1050 Mb assembly on 1,628 scaffolds (72.5 Mb scaffold N50). Species-specific transcript mapping and gene annotation revealed high structural and functional completeness (94.6% BUSCO completeness). Further scaffolding against the high-quality zebra finch (Taeniopygia guttata) genome assigned 98.6% of the assembly to 32 putative nuclear chromosome scaffolds. Rapid, recent advances in sequencing technologies and bioinformatics software have highlighted the need for evidence-based assessment of assembly decisions on a case-by-case basis. Using S. vulgaris vAU, we demonstrate how the multifunctional use of PacBio Iso-Seq transcript data and complementary homology-based annotation of sequential assembly steps (assessed using a new tool, SAAGA) can be used to assess, inform, and validate assembly workflow decisions. We also highlight some counter-intuitive behaviour in traditional BUSCO metrics, and present BUSCOMP, a complementary tool for assembly comparison designed to be robust to differences in assembly size and base-calling quality. Finally, we present a second starling assembly, S. vulgaris vNA, to facilitate comparative analysis and global genomic research on this ecologically important species.

Thursday, 18 March 2021

Chromosome-length genome assembly and structural variations of the primal Basenji dog (Canis lupus familiaris) genome

Our latest genome paper is now out at BMC Genomics. This was a second collaboration in the team behind the German Shepherd Dog genome last year, led by Bill Ballard. This time, we used a combination of BGI short reads, ONT long reads, and Hi-C scaffolding to generate a chromosome-length assembly. This is one of the most intact and complete dog genomes generated to date, and joins only a handful of published breed-specific chromosome-length assemblies.

The Basenji is particularly interesting as it sits at the base of the dog breed family tree, making it a good unbiased reference for future comparisons between breeds.

The paper also has a few nice nuggets for those interesting in genome assembly. Of particular interest, our initial assembly had an artefact where the entire mitochondrial genome got assembled (in two copies) into the middle of one of the nuclear chromosomes. It is not entirely clear why this happened, but it was inserted into a NUMT (nuclear mitochondrial DNA insertion) fragment at that location. To make finding such things easier, we’ve released a new NUMT finding tool, NUMTFinder.

As with our previous dog genome, the German Shepherd Dog, we also observe that the tandem repeat of Amy2B (Amylase Alpha 2B) genes, was assembled intact but with fewer copies than are present in the actual genome. (This gene is of interest for dog domestication and adaptations to a starch-rich diet.) Crucially, without looking at the raw sequencing data, it would not have been clear that the assembly under-represents Amy2B copy number. This kind of analysis can be repeated using the regcheck or regcnv run modes of Diploidocus, which estimates the copy number of a region based on its read depth versus the single-copy read depth determined from BUSCO single-copy complete genes.

Overall, this presents a nice case study of the need for a bit of TLC and manual curation, even when you have some very impressive completeness and contiguity statistics.


Edwards RJ, Field MA, Ferguson JM, Dudchenko O, Keilwagen K, Rosen BD, Johnson GS, Rice ES, Hillier L, Hammond JM, Towarnicki SG, Omer A, Khan R, Skvortsova K, Bogdanovic O, Zammit RA, Lieberman Aiden E, Warren WC & Ballard JWO (2021): Chromosome-length genome assembly and structural variations of the primal Basenji dog (Canis lupus familiaris) genome. BMC Genomics 22:188

Abstract

Background: Basenjis are considered an ancient dog breed of central African origins that still live and hunt with tribesmen in the African Congo. Nicknamed the barkless dog, Basenjis possess unique phylogeny, geographical origins and traits, making their genome structure of great interest. The increasing number of available canid reference genomes allows us to examine the impact the choice of reference genome makes with regard to reference genome quality and breed relatedness.

Results: Here, we report two high quality de novo Basenji genome assemblies: a female, China (CanFam_Bas), and a male, Wags. We conduct pairwise comparisons and report structural variations between assembled genomes of three dog breeds: Basenji (CanFam_Bas), Boxer (CanFam3.1) and German Shepherd Dog (GSD) (CanFam_GSD). CanFam_Bas is superior to CanFam3.1 in terms of genome contiguity and comparable overall to the high quality CanFam_GSD assembly. By aligning short read data from 58 representative dog breeds to three reference genomes, we demonstrate how the choice of reference genome significantly impacts both read mapping and variant detection.

Conclusions: The growing number of high-quality canid reference genomes means the choice of reference genome is an increasingly critical decision in subsequent canid variant analyses. The basal position of the Basenji makes it suitable for variant analysis for targeted applications of specific dog breeds. However, we believe more comprehensive analyses across the entire family of canids is more suited to a pangenome approach. Collectively this work highlights the importance the choice of reference genome makes in all variation studies.

Thursday, 2 April 2020

Canfam_GSD: De novo chromosome-length genome assembly of the German Shepherd Dog (Canis lupus familiaris) using a combination of long reads, optical mapping, and Hi-C

Our latest paper is out! This one is a bit more photogenic than the cane toad - a German Shepherd Dog called Nala. This was a big international effort in a collaboration led by Bill Ballard at UNSW that included a dozen institutions across four continents. We threw all the main sequencing technologies at this one and achieved a chromosome-level assembly of better quality than the current “CanFam” reference genome.

You can find out more in the UNSW press release.


Field MA, Rosen BD, Dudchenko O, Chan EKF, Minoche AM, Edwards RJ, Barton K, Lyons RJ, Enosi Tuipulotu D, Hayes VM, Omer AD, Colaric Z, Keilwagen J, Skvortsova K, Bogdanovic O, Smith MA, Lieberman Aiden E, Smith TPL, Zammit RA & Ballard JWO (2020): Canfam_GSD: De novo chromosome-length genome assembly of the German Shepherd Dog (Canis lupus familiaris) using a combination of long reads, optical mapping, and Hi-C. GigaScience 9(4):giaa027. [GigaScience]


Abstract

Background

The German Shepherd Dog (GSD) is one of the most common breeds on earth and has been bred for its utility and intelligence. It is often first choice for police and military work, as well as protection, disability assistance, and search-and-rescue. Yet, GSDs are well known to be susceptible to a range of genetic diseases that can interfere with their training. Such diseases are of particular concern when they occur later in life, and fully trained animals are not able to continue their duties.

Findings

Here, we provide the draft genome sequence of a healthy German Shepherd female as a reference for future disease and evolutionary studies. We generated this improved canid reference genome (CanFam_GSD) utilizing a combination of Pacific Bioscience, Oxford Nanopore, 10X Genomics, Bionano, and Hi-C technologies. The GSD assembly is ∼80 times as contiguous as the current canid reference genome (20.9 vs 0.267 Mb contig N50), containing far fewer gaps (306 vs 23,876) and fewer scaffolds (429 vs 3,310) than the current canid reference genome CanFamv3.1. Two chromosomes (4 and 35) are assembled into single scaffolds with no gaps. BUSCO analyses of the genome assembly results show that 93.0% of the conserved single-copy genes are complete in the GSD assembly compared with 92.2% for CanFam v3.1. Homology-based gene annotation increases this value to ∼99%. Detailed examination of the evolutionarily important pancreatic amylase region reveals that there are most likely 7 copies of the gene, indicative of a duplication of 4 ancestral copies and the disruption of 1 copy.

Conclusions

GSD genome assembly and annotation were produced with major improvement in completeness, continuity, and quality over the existing canid reference. This resource will enable further research related to canine diseases, the evolutionary relationships of canids, and other aspects of canid biology.

Photo credit: Outdoor Action Photography.

Friday, 31 January 2020

Research snapshot - January 2020

One of the most important, interesting and challenging questions in biology is how new traits evolve at the molecular level. My lab employs sequence analysis techniques to interrogate DNA and protein sequences for the signals left behind by evolution. We are a bioinformatics lab but like to incorporate bench/field data through collaboration wherever possible.

Main Research

Building on a solid foundation of bioinformatics and evolutionary theory, we apply genomics, transcriptomics, proteomics and interactomics and systems analysis to understand complex biological systems. Core research activities can be broadly divided into two main themes:

  1. Evolutionary Genomics, with a focus on applying de novo genome assembly and population genomics to problems in ecology and biotechnology.

  2. Protein-protein interactions, with a focus on the prediction of short linear interaction motifs and their role in human health and disease, including host-pathogen interactions.

These are explored in more detail, below.

1. Evolutionary Genomics.

The main research focus of the lab is the exploitation of genomic and post-genomic data to understand biological function and adaptation to novel environments. We work closely with the Ramaciotti Centre for Genomics and are involved in numerous de novo whole genome sequencing and assembly projects, using short read (Illumina), long read (PacBio & Nanopore) and linked read (10x Chromium) sequencing. One of the biggest of these is leading the bioinformatics and assembly effort in a consortium to sequence the cane toad genome, and leading the BABS Genome project to sequence two iconic Australian snakes. We are a member of the Oz Mammals Genomics initiative, assisting with the sequencing and assembly of Australia’s unique marsupial fauna. In 2018, we were selected as part of a team to sequence the Waratah genome as part of the pilot phase for the new Genomics of Australian Plants initiative.

We enjoy bringing our bioinformatics to bear on a variety of collaborative research projects. Most notably, we have an ARC Linkage Grant with Microbiogen Pty Ltd to understand how a strain of Saccharomyces cerevisiae has evolved to efficiently use xylose as a sole carbon source: something vital for second generation biofuel production that wild yeast cannot do. We are combining comparative genomics, evolutionary genetics, RNA-Seq transcriptomics, and competition assays to understand how the novel metabolism evolved. Through deep Illumina resequencing of evolving populations, and assembling reliable complete genomes of the founding ancestors, the ultimate goal is to trace how mutations have interacted with existing genetic variation during adaptive evolution. More recently, we have received an ARC Linkage Grant with the Royal Botanic Gardens and Domain Trust, to apply genomics approaches to the challenges of rainforest tree conservation in the face of climate change and invasive pathogens. We are also collaborating with industrial and academic partners to de novo sequence, assemble, annotate and interrogate the genomes of a selection of microbes with interesting metabolic abilities.

2. Short Linear Motifs (SLiMs).

Many protein-protein interactions are mediated by Short Linear Motifs (SLiMs): short stretches of proteins (5-15 amino acids long), of which only a few positions are critical to function. These motifs are vital for biological processes of fundamental importance, acting as ligands for molecular signalling, post-translational modifications and subcellular targeting. SLiMs have extremely compact protein interaction interfaces, generally encoded by less than 4 major affinity-/specificity-determining residues. Their small size enables high functional density and evolutionary plasticity, making them frequent products of convergent “ex nihilo” evolution. It also makes them challenging to identify, both experimentally and computationally.

A major focus of the lab is the computational prediction of SLiMs from protein sequences. This research originated with Rich’s postdoctoral research, during which he developed a sequence analysis methods for the rational design of biologically active short peptides. He subsequently developed SLiMDisc, one of the first algorithms for successfully predicting novel SLiMs from sequence data - and coined the term “SLiM” into the bargain. This subsequently lead to the development of SLiMFinder, the first SLiM prediction algorithm able to estimate the statistical significance of motif predictions. SLiMFinder greatly increased the reliability of predictions. SLiMFinder has since spawned a number of motif discovery tools and webservers and is still arguably the most successful SLiM prediction tool on benchmarking data. Methods are made available through the SLiMSuite bioinformatics package and webservers.

Current research is looking to develop these SLiM prediction tools further and apply them to important biological questions. Of particular interest is the molecular mimicry employed by viruses to interact with host proteins and the role of SLiMs in other diseases, such as cancer. Other work is concerned with the evolutionary dynamics of SLiMs within protein interaction networks.

OTHER RESEARCH PROJECTS

In addition to the main research in the lab, the lab has a number of interdisciplinary collaborative projects applying bioinformatics tools and molecular evolution theory to experimental biology, often using large genomic, transcriptomic and/or proteomic datasets. These projects often involve the development of bespoke bioinformatics pipelines and a number of open source bioinformatics tools have been generated as a result. Please see the Publications and Lab software pages for more detail, or get in touch if something catches your eye and you want to find out more. We frequently have small collaborations and/or undergraduate student research projects. Many of these are “on hold” waiting for the right person, or sometimes data, to come along. If you think that you have what it needs, get in touch!

Friday, 5 July 2019

Research snapshot - July 2019

One of the most important, interesting and challenging questions in biology is how new traits evolve at the molecular level. My lab employs sequence analysis techniques to interrogate protein and DNA sequences for the signals left behind by evolution. We are a bioinformatics lab but like to incorporate bench data through collaboration wherever possible.

Main Research

The core research in the lab is broadly divided into two main themes:

1. Evolutionary Genomics.

Since moving to UNSW, a major focus of the lab has been the exploitation of genomic and post-genomic data to understand biological function and adaptation to novel environments. We work closely with the Ramaciotti Centre for Genomics and are involved in numerous de novo whole genome sequencing and assembly projects, using short read (Illumina), long read (PacBio & Nanopore) and linked read (10x Chromium) sequencing. The biggest of these is leading the bioinformatics and assembly effort in a consortium to sequence the cane toad genome, and leading the BABS Genome project to sequence two iconic Australian snakes. We are a member of the Oz Mammals Genomics initiative, assisting with the sequencing and assembly of Australia’s unique marsupial fauna. In 2018, we were selected as part of a team to sequence the Waratah genome as part of the pilot phase for the new Genomics of Australian Plants initiative.

We enjoy bringing our bioinformatics to bear on a variety of collaborative research projects. Most notably, we have an ARC Linkage Grant with Microbiogen Pty Ltd to understand how a strain of Saccharomyces cerevisiae has evolved to efficiently use xylose as a sole carbon source: something vital for second-generation biofuel production that wild yeast cannot do. We are combining comparative genomics, evolutionary genetics, RNA-Seq transcriptomics, and competition assays to understand how the novel metabolism evolved. Through deep Illumina resequencing of evolving populations, and assembling reliable complete genomes of the founding ancestors, the ultimate goal is to trace how mutations have interacted with existing genetic variation during adaptive evolution. More recently, we have received an ARC Linkage Grant with the Royal Botanic Gardens and Domain Trust, to apply genomics approaches to the challenges of rainforest tree conservation in the face of climate change and invasive pathogens. We are also collaborating with industrial and academic partners to de novo sequence, assemble, annotate and interrogate the genomes of a selection of microbes with interesting metabolic abilities.

2. Short Linear Motifs (SLiMs).

Many protein-protein interactions are mediated by Short Linear Motifs (SLiMs): short stretches of proteins (5-15 amino acids long), of which only a few positions are critical to function. These motifs are vital for biological processes of fundamental importance, acting as ligands for molecular signalling, post-translational modifications and subcellular targeting. SLiMs have extremely compact protein interaction interfaces, generally encoded by less than 4 major affinity-/specificity-determining residues. Their small size enables high functional density and evolutionary plasticity, making them frequent products of convergent “ex nihilo” evolution. It also makes them challenging to identify, both experimentally and computationally.

A major focus of the lab is the computational prediction of SLiMs from protein sequences. This research originated with Rich’s postdoctoral research, during which he developed a sequence analysis methods for the rational design of biologically active short peptides. He subsequently developed SLiMDisc, one of the first algorithms for successfully predicting novel SLiMs from sequence data - and coined the term “SLiM” into the bargain. This subsequently lead to the development of SLiMFinder, the first SLiM prediction algorithm able to estimate the statistical significance of motif predictions. SLiMFinder greatly increased the reliability of predictions. SLiMFinder has since spawned a number of motif discovery tools and webservers and is still arguably the most successful SLiM prediction tool on benchmarking data. Methods are made available through the SLiMSuite bioinformatics package and webservers.

Current research is looking to develop these SLiM prediction tools further and apply them to important biological questions. Of particular interest is the molecular mimicry employed by viruses to interact with host proteins and the role of SLiMs in other diseases, such as cancer. Other work is concerned with the evolutionary dynamics of SLiMs within protein interaction networks.

OTHER RESEARCH PROJECTS

In addition to the main research in the lab, the lab has a number of interdisciplinary collaborative projects applying bioinformatics tools and molecular evolution theory to experimental biology, often using large genomic, transcriptomic and/or proteomic datasets. These projects often involve the development of bespoke bioinformatics pipelines and a number of open source bioinformatics tools have been generated as a result. Please see the Publications and Lab software pages for more detail, or get in touch if something catches your eye and you want to find out more. We frequently have small collaborations and/or undergraduate student research projects. Many of these are “on hold” waiting for the right person, or sometimes data, to come along. If you think that you have what it needs, get in touch!